Quotas & Billing
Every account carries a metered balance so that testing stays predictable and one runaway simulation can't consume the service. Nothing is charged to you personally — the balance is an allowance, and when it runs out you ask for more.
Two balances, not one
Spending is split across two planes, because they behave completely differently:
| plane | what it pays for | default |
|---|---|---|
| Agent | the research assistant's own reasoning — every conversational turn, every artifact it writes | $10.00 |
| Simulation | what the simulated world costs: the agents' LLM decisions during a run, and calls to external data services | $10.00 |
Accounts registered with an invite code start higher, at $50 + $50.
Splitting them means a long design conversation can't quietly eat the budget you were saving for the run, and vice versa.
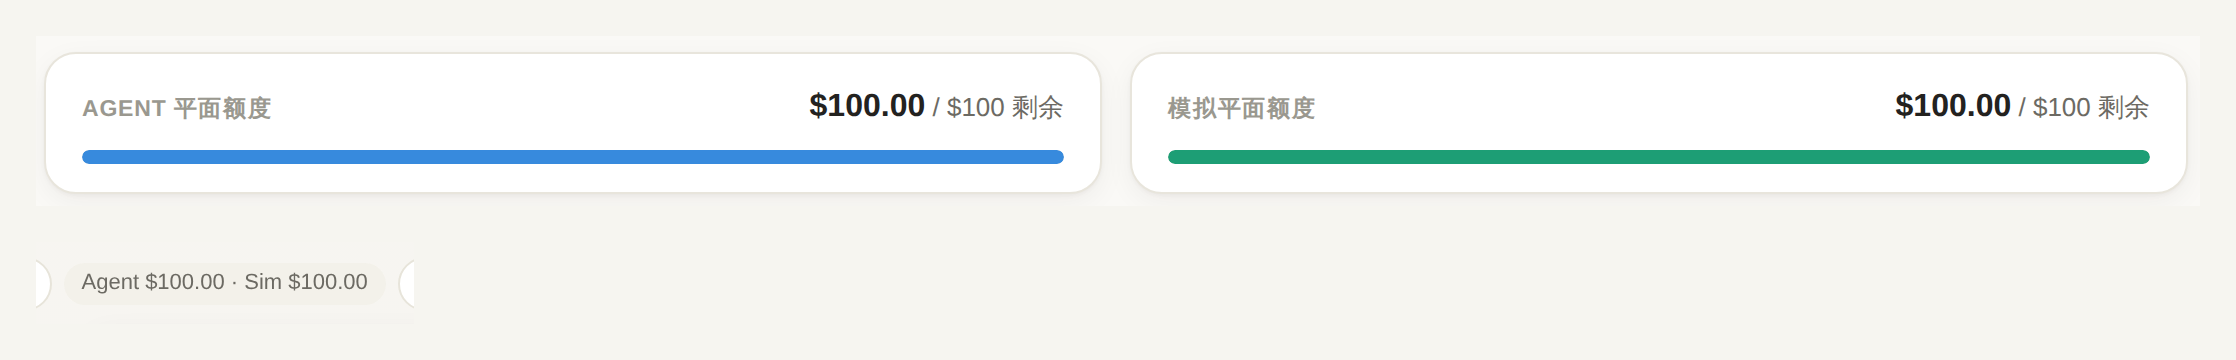
Both balances are shown as Agent $x.xx · Sim $y.yy in the top bar of a study,
and as two cards with progress bars on the study list. The chip turns amber when
either plane drops below $1.
What things cost
Conversation draws on the agent plane, per turn, in proportion to how much reading and writing the turn required. Ordinary back-and-forth is cheap; building a model from scratch is not.
Simulation runs draw on the sim plane. The cost scales with the population size times the horizon — every agent, every step, is a decision. A 20-agent, 4-step study is a few cents; a 500-agent, 12-step study is a different conversation, which is why the assistant states the configuration and its estimate before running.
External capabilities are metered per call:
| capability | how it's charged |
|---|---|
Population survey simulation (run_user_pool_distribution_simulation) |
per simulated respondent — one questionnaire answer per person, so the cost scales directly with the requested user_count |
| Population index build | a flat one-off charge |
| Event / real-world data lookups | a small flat charge per call |
All three hit the sim plane. The per-respondent survey call is the one to watch: asking for 2,000 respondents costs a hundred times what 20 costs, and it is easy to type a large number without meaning it.
External calls are not free lookups
A population survey call runs a real LLM questionnaire for every simulated respondent, and event lookups hit a real service. The assistant is required to tell you the expected spend — including the respondent count — and get your agreement before making one, and a line appears in the conversation recording each charge after the fact. Read those lines; they are the ground truth of what you've spent.
See External Capabilities for what these services actually do.
What you're asked before spending
- Before a real simulation run, you get an explicit cost confirmation: the configuration, the estimate, and a question card you have to answer. A study running on rule-based (scripted) decisions spends nothing on the sim plane and isn't gated this way.
- Before an external capability call, the assistant states the expected cost and asks.
- After each charge, a line in the conversation names the tool and the amount, and the top-bar chip refreshes.
Keep an eye on the running total
The confirmation you give at the start of a session covers the work you agreed to; it isn't a per-command receipt. If you're iterating quickly through several runs, the balance chip in the top bar is the number to watch, not your memory of what you approved.
Running out
When the agent plane is exhausted, new messages are refused — the conversation reports that the balance is used up and asks you to contact the team for a top-up. Existing studies and results are untouched; you simply can't start new work until the balance is raised.
When the sim plane runs low, the assistant should decline to start a run it can't afford and tell you so. Because the sim plane pays for external services too, it's worth checking the chip before a large survey call.
Top-ups are manual: ask the team, and both planes can be raised independently.
Making a budget go further
- Design at small scale, then scale up. Get the environment, the population and the metrics right with 20 agents over 4 steps. Multiplying afterwards is one parameter change; discovering a modelling mistake at 500 agents is an expensive lesson.
- Use a dry run to prove the plumbing. A scripted decision path exercises the whole loop for free. Only switch to real LLM decisions when the mechanics work — that's exactly what LLM Clients & Dry Runs is for.
- Extend, don't restart. When an iteration only changes what happens from step J onward, a warm start replays the earlier steps from stored results instead of re-paying for them. See warm starts.
- Ask for the smallest survey that answers the question. Respondent count is the single largest lever on external cost.
- Take big runs local. If a study genuinely needs thousands of agents, clone the open-source package and run it with your own key. The study directory is the same.